The small studies that found nothing sit in drawers. The ones that got lucky are in journals.
Suppose a trial of twenty patients finds a new blood pressure drug does nothing significant, and a second trial of twenty finds p = 0.03. Most readers conclude it failed once and worked once, which confuses two concepts. The p-value tells you how surprised you should be if the null hypothesis were true. Statistical power tells you whether the study had any chance of detecting the effect in the first place.
Surprise, not truth
The p-value answers a narrow question: if nothing were going on, how often would I see data this extreme? That is P(data | null), not P(null | data), and inverting the two is the most common misread in applied statistics. Nor does the p-value measure size: with a million participants, a drug that lowers blood pressure by 0.1 mmHg can hit p < 0.01. The effect is real and completely useless.
The dim flashlight
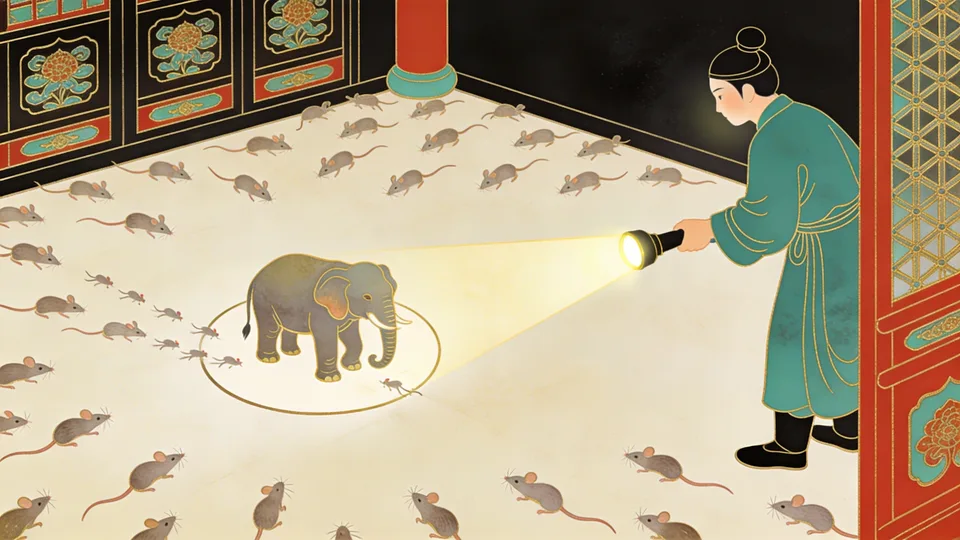
Think of a study as a flashlight in a dark room. The p-value tells you whether what you saw in the beam is surprising; power, which grows with sample size and effect size, is how bright the flashlight is. With twenty patients the beam is dim. Only elephant-sized effects show up, while the subtle effects that make up most of what matters in medicine, finance and social science walk past like mice.
So the first trial said less than it seemed. A study that fails to find an effect with low power has told you almost nothing: the effect was not elephant-sized, and that is all. Absence of evidence is evidence of absence only when the flashlight was bright enough.
The second trial is shakier. Most studies are underpowered, because adequate samples are expensive, and journals do not reward null results. Underpowered studies that happen to cross p < 0.05 get published; those that find nothing get filed away. The literature fills with flukes and inflated effects, which drives the replication crisis through selection rather than fraud.
Swapping p-values for Bayesian methods is directionally right but misses this: better tools inside the same incentives produce the same distortions. The fixes that touch the filter are pre-registration, mandatory power analysis and journals that publish null results. Meanwhile, ask of any study whether it could have detected a realistic effect at all. If the answer is “barely,” a null finding is uninformative and a significant one is more likely noise than signal. In underpowered fields, the elephants in the beam are often shadows.
References
- Notes on Statistics Done Wrong, Moontower Meta