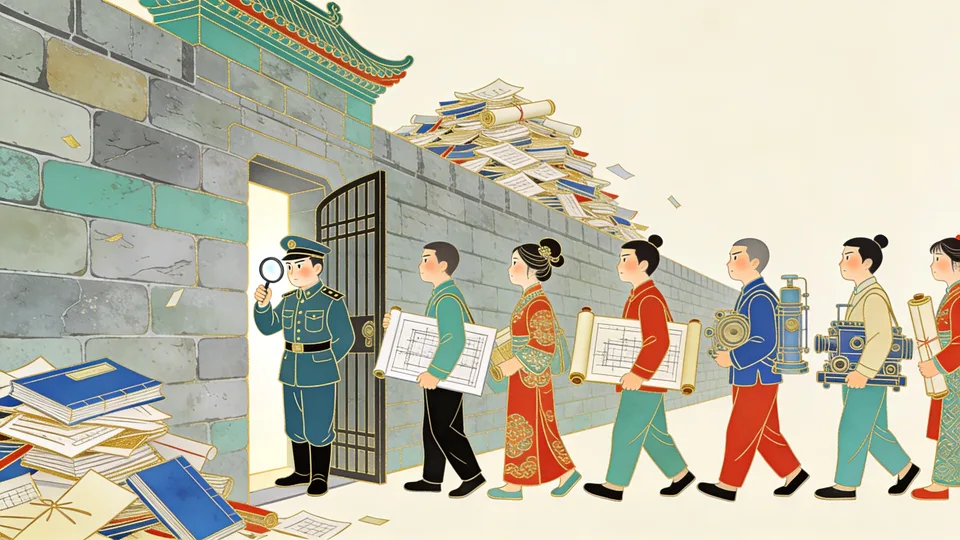
Every review counts what it caught. Almost none count what it killed.
A reviewer opens your change, reads just far enough to find one nitpick, and stops. You fix it the same afternoon. The next day they read a little further and find another nitpick they could have mentioned the first time. Each round trip costs a day. A week later the change has barely moved, and the reviewer can truthfully say they responded promptly to every revision and raised only legitimate issues.
Was that reviewer being careful or obstructive? The common assumption is that a close look would tell you, and that the cure for bad reviewing is clearer review guidelines. Simon Tatham’s catalogue of code review antipatterns, the source of this case, suggests otherwise. The danger of each pattern is that it is indistinguishable from legitimate diligence.
The asymmetry inside every gate
Any process that requires someone’s approval before work can proceed creates a structural power asymmetry. The approver can always say no, and the burden of proof always sits with the person seeking approval. In the round-trip case, the reviewer broke no rule. The dysfunction lies in working serial where parallel was possible, and no rule requires parallel feedback.
The other patterns in the catalogue use the same asymmetry. In the Catch-22, one large patch is “too hard to review — split it up,” while many small patches “don’t make sense on their own — combine them.” In the Guessing Game, the reviewer rejects a design on vague grounds such as “future compatibility” without saying what would pass, so they never commit to a position and can never be wrong. Each move rests on a concern a careful reviewer might genuinely hold, which gives the gatekeeper plausible deniability: thoroughness looks the same whether it is driven by quality or by power.
Most gatekeepers are not doing this on purpose. They are doing what the system rewards, which is demonstrating value through criticism rather than through contribution. The gate pays for finding problems and never for solving them, and a reviewer who approves quickly looks as if they did nothing.
That is why guidelines fail. Require all feedback in one pass, and the second pass arrives as “new concerns.” Require specific objections, and the objections become specific about trivia. The lesson generalizes: no amount of process documentation prevents power dynamics from flowing through the approved channels. What changes behavior is accountability for the reviewer’s impact on throughput: measuring not just what a review caught but what it blocked, delayed or killed.
Gates worth keeping
None of this means review should go. Shipping without review swaps one failure for another, because some gates do real work. They are sacred friction, preserving contact with reality by catching the bug or the bad design before users meet it. Others merely preserve the gatekeeper’s status. The whole diagnostic problem is telling those two apart before high-agency bypassing hardens into contempt for all constraint. Since the round-trip reviewer and the careful one leave identical comments, the difference shows only in aggregate: how long changes wait, and how often a review stops something that mattered.
The cost of failing to tell them apart arrives slowly. Junior submitters have no standing to challenge a gatekeeper, so they comply and learn that voice is futile. The engineers who care most about good work are the least willing to tolerate weaponized review, and they leave, which is the The Dead Sea Effect at work. Those who remain have learned to appease gatekeepers rather than build good software, and they become the next generation of reviewers.
Nothing here is specific to code. Editorial review, design critique, legal sign-off and procurement approval all hand one party a veto and the other the burden of proof, and they show the same patterns. Most of them count what they catch. Very few count what they kill, and a gate that has never been asked that question cannot know which kind it is.
References:
- Simon Tatham, Code Review Antipatterns